

Hongxia Xie (谢洪霞)
Jilin University
I am an associate professor (tenure-track) in the College of Computer Science and Technology at Jilin University, China, and serve as the principal investigator of the Affective Vision and Computing (AVC) Lab. My research interests include multimodal affective computing and generative AI. Our mission is to bridge the affective gap between machines and humans. I received my Ph.D. degree from the Institute of Electronics of National Yang Ming Chiao Tung University (NYCU) under the supervision of Prof. Wen-Huang Cheng (IEEE Fellow) and the co-supervision of Prof. Hong-Han Shuai. Over the past five years, I have published nearly 20 academic papers in top-tier venues such as CVPR, ICCV, ECCV, ACM Multimedia, AAAI, IEEE Transactions on Affective Computing, and IEEE Transactions on Cybernetics. One of my papers also received the Best Paper Award at IEEE ICME 2021.
🔥News
- 🔥[2026/07]: We have released our survey on Social World Models, which introduces a three-level analytical framework covering Individual Agency, Mental Inference, and Social Coordination. The survey provides a comprehensive review of representative methods, datasets, and benchmarks across embodied intelligence, Theory of Mind, affective computing, human–robot collaboration, and multi-agent social coordination. We warmly invite you to explore the full survey at the link: https://github.com/avclabjlu/Awesome-Social-World-Models. We hope it will serve as a useful resource for researchers interested in socially intelligent AI.
- 🔥[2026/03]: We launch the AffectiveArt 2026: Fine-Grained Emotion Understanding & Generation in Artistic Images Grand Challenge at ACM MM 2026. For details, please visit affectiveart-challenge.github.io. We warmly welcome your participation.
- 🔥[2026/02]: Four papers got accepted by CVPR 2026 🎉
- 🔥[2025/12]: One paper got accepted by AAAI 2026 🎉
- 🔥[2025/07]: Two papers got accepted by ACM Multimedia 2025 (Datasets Track) 🎉
- 🔥[2025/07]: One paper got accepted by ACM Multimedia 2025 🎉
- 🔥[2025/07]: One paper got accepted by ICCV 2025 🎉
- 🔥[2025/01]: I am awarded the Leading Talent Title by Jilin Province Government, China 🎉
- 🔥[2024/12]: One paper got accepted by AAAI 2025 🎉
- 🔥[2024/11]: I will serve as the Grand Challenge Co-chairs of ACM Multimedia 2025 🎉
- 🔥[2024/08]: I receive the Youth Project Funding from National Natural Science Foundation of China (funding rate of 15.54%) 🎉
- 🔥[2024/07]: I won the Best Poster Award in China Affective Computing Conference 🎉
- 🔥[2024/07]: One paper got accepted by ECCV 2024 🎉
- 🔥[2024/04]: One paper got accepted by ACM Computing Survey 🎉
- 🔥[2024/02]: One paper got accepted by CVPR 2024 🎉
- 🔥[2023/10]: One paper got accepted by ICCE 2024 🎉
- 🔥[2023/07]: One paper got accepted by ICCV 2023 🎉
- 🔥[2023/06]: One paper got accepted by IEEE Transactions on Affective Computing 🎉
🔥Enrollment Quota Notice:
- My PhD positions for 2026 are already filled. There will be 1–2 positions available for the 2027 Fall. Interested students are welcome to contact me via email.
- There are 3 master’s openings for the 2027 Fall.
- Remote research assistants are welcome.
添加一个应用工具
或者你可以输入 HTML 代码(专业版以上功能)
Affective Vision Computing LabIntelligence that understands people and the physical world.
We develop human-centered AI that connects emotion, social reasoning, and realistic visual generation. Led by Associate Professor Hongxia Xie at Jilin University, AVC Lab studies how intelligent systems can understand people, create expressive visual experiences, and act in the world.
Meet AVC Lab College of Computer Science and Technology
Jilin University · Changchun, ChinaUnderstanding people.
Connecting perception, reasoning, and action.From the labNews.
Research milestones, awards, and community activities.
We have released our survey on Social World Models, which introduces a three-level analytical framework covering Individual Agency, Mental Inference, and Social Coordination. The survey provides a comprehensive review of representative methods, datasets, and benchmarks across embodied intelligence, Theory of Mind, affective computing, human–robot collaboration, and multi-agent social coordination. We warmly invite you to explore the full survey at the link: https://github.com/avclabjlu/Awesome-Social-World-Models. We hope it will serve as a useful resource for researchers interested in socially intelligent AI.
Mind-CAD was accepted by Computer-Aided Design and is now available online. Read the paper ↗
We launch the AffectiveArt 2026: Fine-Grained Emotion Understanding & Generation in Artistic Images Grand Challenge at ACM MM 2026. For details, please visit affectiveart-challenge.github.io. We warmly welcome your participation.
Four papers got accepted by CVPR 2026 🎉
One paper got accepted by AAAI 2026 🎉
Two papers got accepted by ACM Multimedia 2025 (Datasets Track) 🎉
One paper got accepted by ACM Multimedia 2025 🎉
One paper got accepted by ICCV 2025 🎉
I am awarded the Leading Talent Title by Jilin Province Government, China 🎉
One paper got accepted by AAAI 2025 🎉
I will serve as the Grand Challenge Co-chairs of ACM Multimedia 2025 🎉
I receive the Youth Project Funding from National Natural Science Foundation of China (funding rate of 15.54%) 🎉
I won the Best Poster Award in China Affective Computing Conference 🎉
One paper got accepted by ECCV 2024 🎉
One paper got accepted by ACM Computing Survey 🎉
One paper got accepted by CVPR 2024 🎉
One paper got accepted by ICCE 2024 🎉
One paper got accepted by ICCV 2023 🎉
One paper got accepted by IEEE Transactions on Affective Computing 🎉
01 / ResearchFour connected directions.
Our research connects four areas, from understanding human emotions and intentions to generating coherent visual content and improving embodied decision-making.
01Physical AI
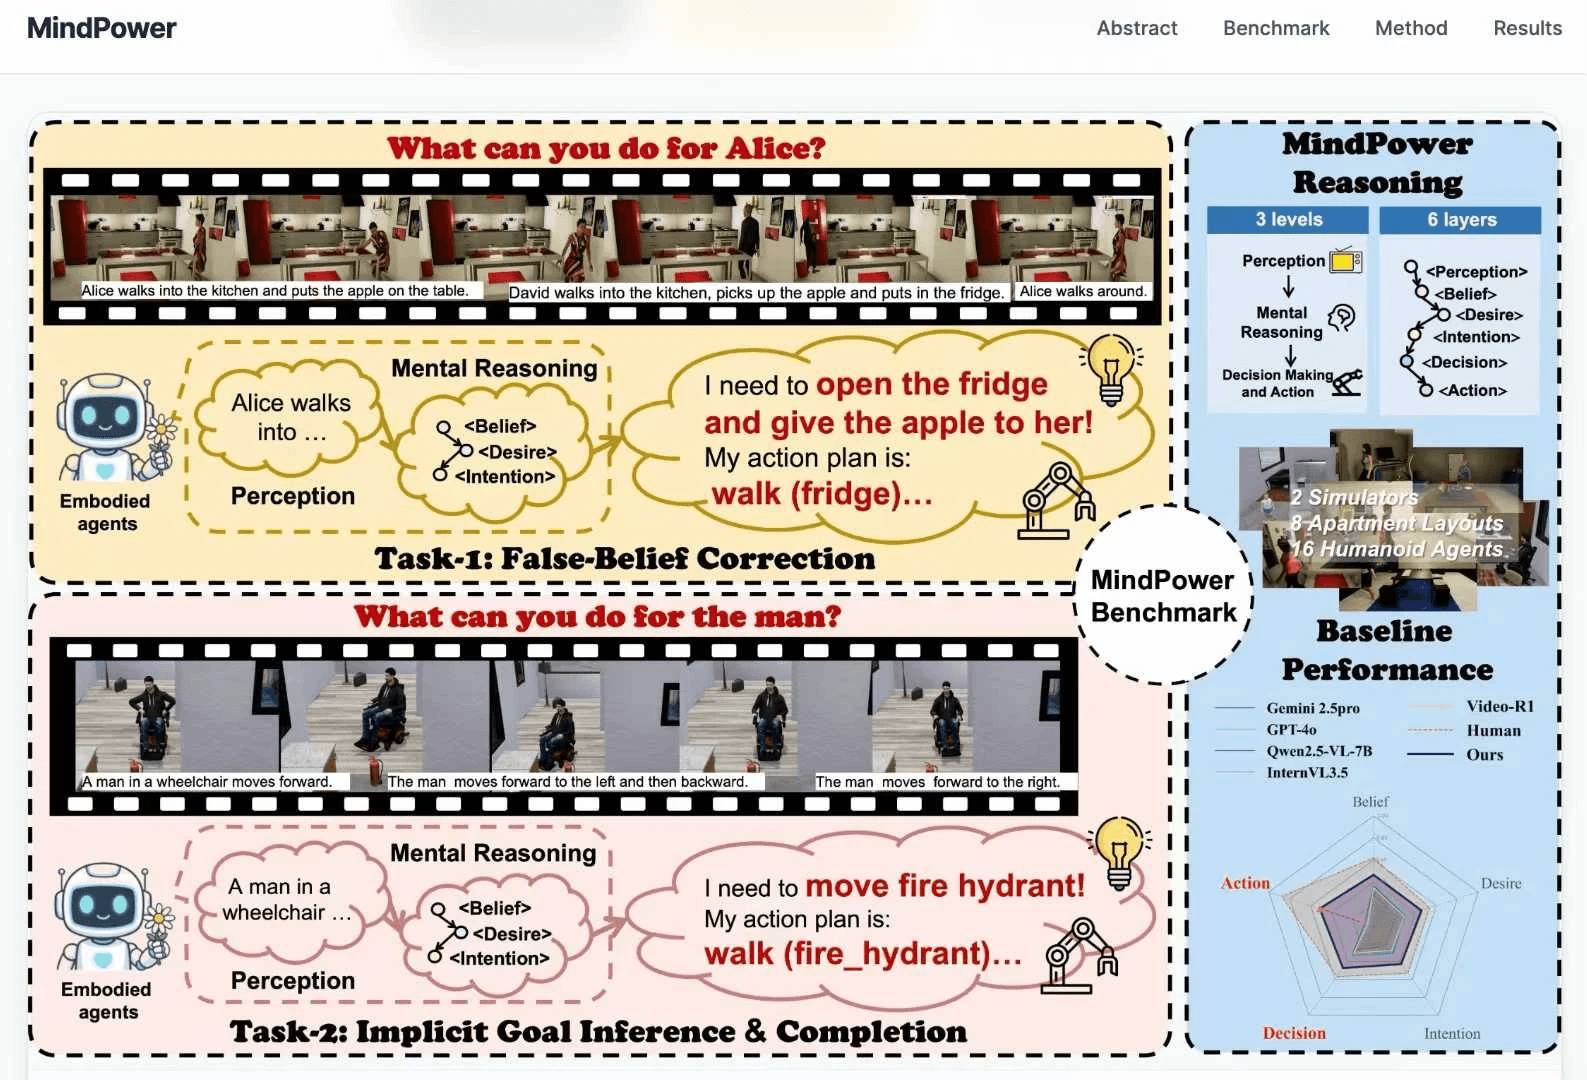
We study social world models, theory of mind, and embodied agents that connect perception, reasoning, and action. Our work asks how machines can infer beliefs and intentions, reason about physical processes, and perform tasks with greater consistency and care.
Explore MindPower →02Realistic Generation
We develop controllable visual generation across artistic images, human relighting, and multimodal design. We focus on the relationship between visual detail, physical consistency, and human intent.
Explore KPLM-STA →03Human-Centered AI
We build models and benchmarks for emotion understanding, affective reasoning, and reliable multimodal interpretation. Our goal is to help intelligent systems understand the rich context behind human expression.
Explore EmoVIT →04AI for Science
We investigate multimodal generation for structured, real-world processes, with a current focus on food computing. Our research links written instructions to coherent visual sequences and step-aligned evaluation.
Explore RecipeGen →Research visionFrom seeing to understanding to acting, we build emotionally intelligent multimodal AI.
Our research enables machines to perceive affect, reason about mental states, and generate socially coherent decisions and behaviors.

Projects & open resources
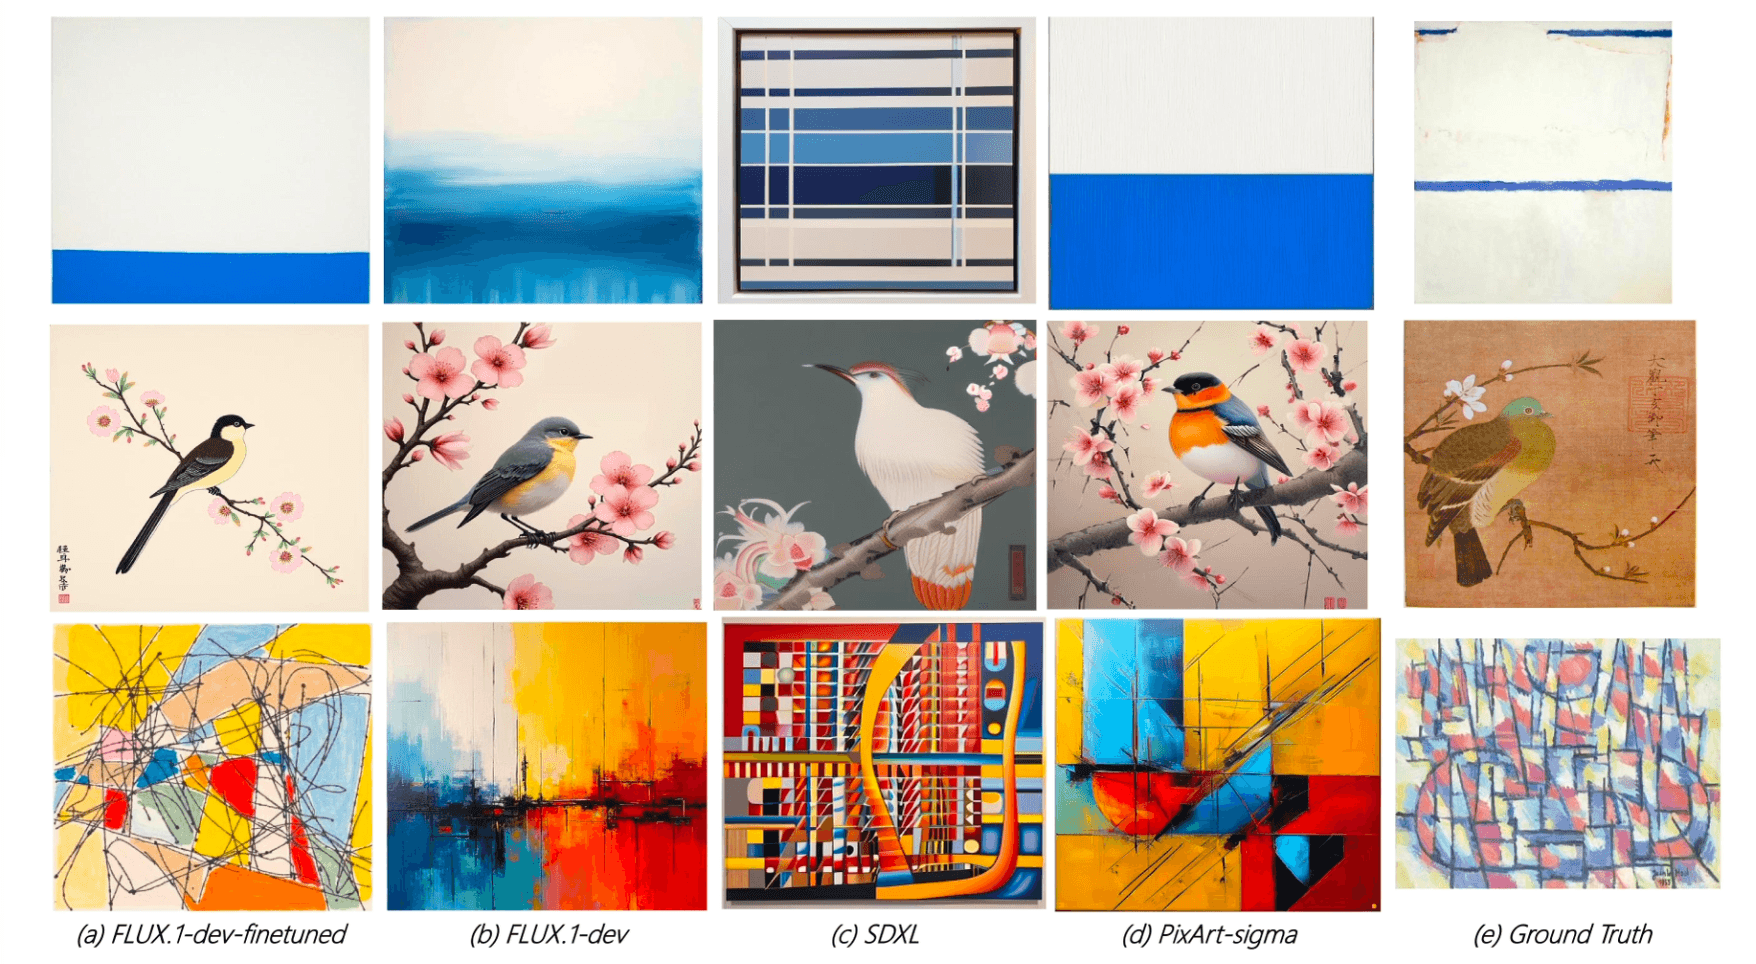
EmoArt (ACM MM 2025)
A Multidimensional Dataset for Emotion-Aware Artistic Generation
Project Page ↗Additional project figure

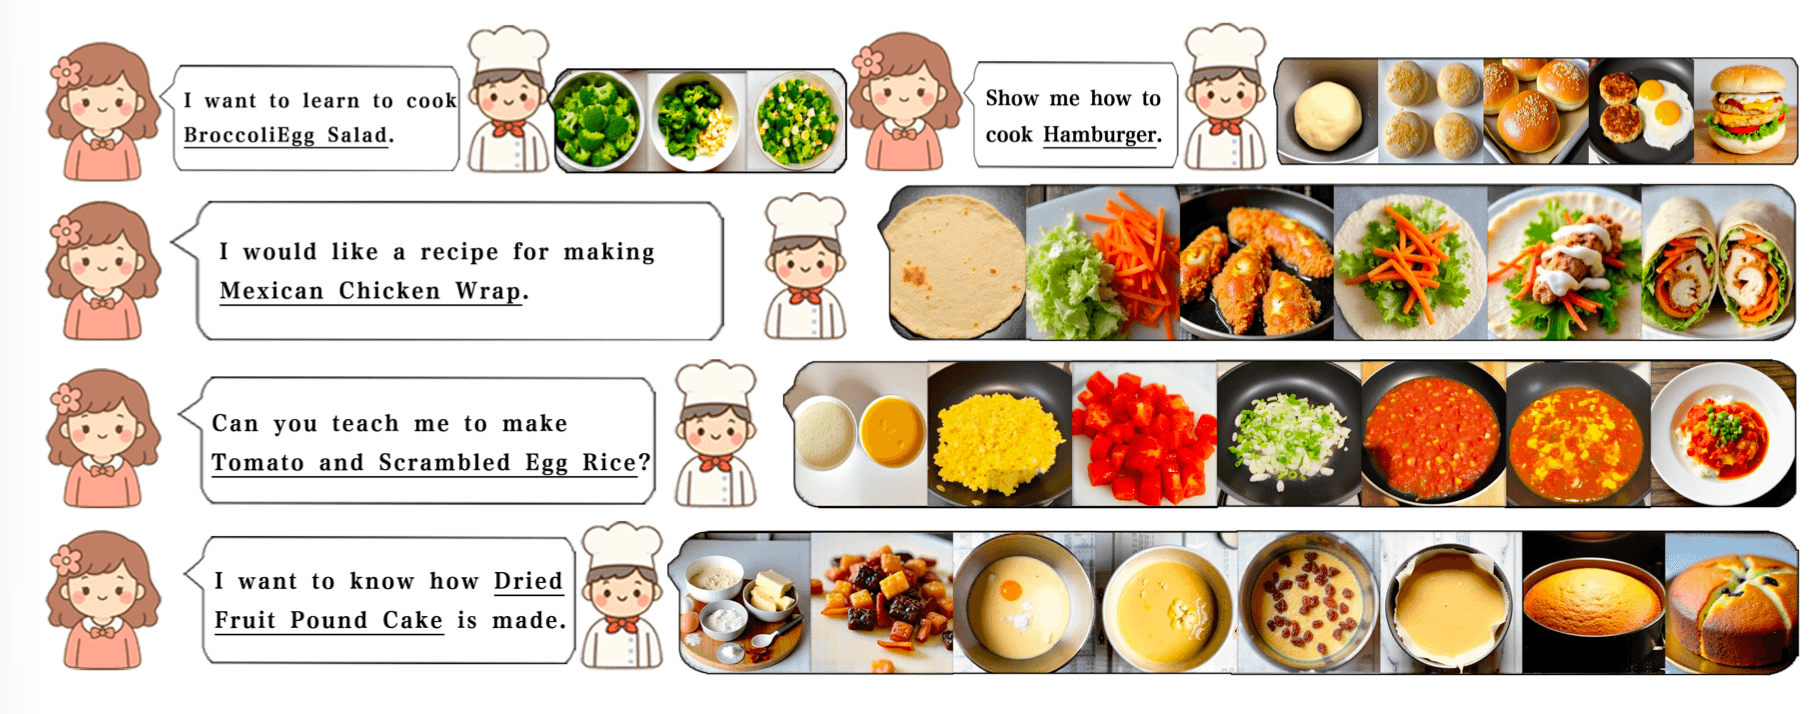
CookAnything (ACM MM 2025)
A Framework for Flexible and Consistent Multi-Step Recipe Image Generation
Project Page ↗
Awesome Social World Models
A Comprehensive Survey of Theory of Mind and Social Coordination
Paper List ↗02 / Selected publicationsIdeas, made concrete.
Selected research from AVC Lab and collaborators.
Explore the papers, methods, datasets, and open resources behind our work.
Full publication list ↓-
MindPower: Enabling Theory-of-Mind Reasoning in VLM-based Embodied Agents
Connecting perception, mental-state reasoning, and action in socially aware embodied agents.
Authors & publication details
Ruoxuan Zhang, Qiyun Zheng, Zhiyu Zhou, Ziqi Liao, Siyu Wu, Jian-Yu Jiang-Lin, Bin Wen, Hongxia Xie, Jianlong Fu, Wen-Huang Cheng.
CVPR 2026, pp. 29631–29641.
Hongxia Xie: corresponding author. -
KPLM-STA: Physically-Accurate Shadow Synthesis for Human Relighting via Keypoint-Based Light Modeling
Physically grounded shadows for human relighting through body keypoints and explicit light geometry.
Authors & publication details
Xinhui Yin, Qifei Li, Yilin Guo, Hongxia Xie, Xiaoli Zhang.
AAAI 2026, 40(14), pp. 12036–12043.
Hongxia Xie and Xiaoli Zhang: corresponding authors. -
EmoArt: A Multidimensional Dataset for Emotion-Aware Artistic Generation
A structured artwork dataset connecting visual attributes, emotion, and artistic generation.
Authors & publication details
Cheng Zhang, Hongxia Xie, Bin Wen, Songhan Zuo, Ruoxuan Zhang, Wen-Huang Cheng.
ACM Multimedia 2025, Datasets Track, pp. 12644–12650.
Hongxia Xie: corresponding author. -
RecipeGen: A Step-Aligned Multimodal Benchmark for Real-World Recipe Generation
Step-aligned recipes, images, and videos for evaluating faithful multimodal recipe generation.
Authors & publication details
Ruoxuan Zhang, Jidong Gao, Bin Wen, Hongxia Xie, Chenming Zhang, Hong-Han Shuai, Wen-Huang Cheng.
ACM Multimedia 2025, Datasets Track, pp. 12659–12665.
Hongxia Xie: corresponding author. -
CookAnything: A Framework for Flexible and Consistent Multi-Step Recipe Image Generation
Flexible recipe illustration that aligns each step with its image while maintaining consistency across the sequence.
Authors & publication details
Ruoxuan Zhang, Bin Wen, Hongxia Xie, Yi Yao, Songhan Zuo, Jian-Yu Jiang-Lin, Hong-Han Shuai, Wen-Huang Cheng.
ACM Multimedia 2025, pp. 7854–7863.
Hongxia Xie: corresponding author. -
EmoVIT: Revolutionizing Emotion Insights with Visual Instruction Tuning
Visual instruction tuning for emotion classification, affective reasoning, and humor understanding.
Authors & publication details
Hongxia Xie, Chu-Jun Peng, Yu-Wen Tseng, Hung-Jen Chen, Chan-Feng Hsu, Hong-Han Shuai, Wen-Huang Cheng.
CVPR 2024, pp. 26596–26605.
Hongxia Xie: first author. -
Beyond Success: Refining Elegant Robot Manipulation from Mixed-Quality Data via Just-in-Time Intervention
Improving robot execution quality through selective interventions without retraining the base policy.
Authors & publication details
Yanbo Mao, Jianlong Fu, Ruoxuan Zhang, Hongxia Xie, Meibao Yao.
CVPR 2026, pp. 13508–13518.
Hongxia Xie: coauthor. Meibao Yao: corresponding author. -
CAD-Refiner: A Unified Framework for CAD Generation and Iterative Editing
A unified approach to multimodal CAD generation and iterative refinement.
Authors & publication details
Meng Yuan, Dawei Lin, Hongxia Xie, Tieru Wu, Rui Ma.
CVPR 2026, pp. 3244–3253.
Hongxia Xie: coauthor. Tieru Wu and Rui Ma: corresponding authors.
Recent preprints
Early research, shared with the community.
JULY 2026
arXiv preprintRead preprint ↗RetroHolmes: When Semantic Plausibility Fails Retrospective Physical Process Reasoning
A benchmark for reasoning backward from visual outcomes under physical constraints.
APRIL 2026
arXiv preprintRead preprint ↗Aligning Progress and Feasibility: A Neuro-Symbolic Dual Memory Framework for Long-Horizon LLM Agents
A dual-memory framework separating semantic progress guidance from logical action validation.
Survey & curated resource Social World Models
A survey and curated reading list connecting individual agency, mental-state inference, emotion, and social coordination.
Explore the resource ↗ACM Multimedia 2026 Grand Challenge AffectiveArt 2026
Fine-grained emotion understanding and generation in artistic images. Challenge results and resources are available.
View results & resources ↗Publication archiveFull publication list.
Journal articles and conference papers, including the complete publication list from Hongxia Xie's homepage.
Google Scholar ↗Journal articles6 publications
- J01
Mind-CAD: An interpretable multimodal framework for image-guided CAD DSL generation and editing
Computer-Aided Design, vol. 199, Article 104126, 2026. Published online June 15, 2026.
- J02
- J03
An Overview of Facial Micro-Expression Analysis: Data, Methodology and Challenge
IEEE Transactions on Affective Computing, 2022. DOI: 10.1109/TAFFC.2022.3143100.
- J04
CA-FER: Mitigating Spurious Correlation With Counterfactual Attention in Facial Expression Recognition
IEEE Transactions on Affective Computing, 15(3), pp. 977–989, 2024. DOI: 10.1109/TAFFC.2023.3312768. * Equal contribution.
- J05
Facial Chirality: From Visual Self-Reflection to Robust Facial Feature Learning
IEEE Transactions on Multimedia, vol. 24, pp. 4275–4284, 2022. DOI: 10.1109/TMM.2022.3197365.
- J06
Specific Expert Learning: Enriching Ensemble Diversity via Knowledge Distillation
IEEE Transactions on Cybernetics, pp. 1–12, 2021. DOI: 10.1109/TCYB.2021.3125320.
Conference papers19 publications
- C01
- C02
- C03
CAD-Refiner: A Unified Framework for CAD Generation and Iterative Editing
CVPR 2026, pp. 3244–3253.
- C04
- C05
- C06
- C07
- C08
- C09
- C10
Foreground Focus: Enhancing Coherence and Fidelity in Camouflaged Image Generation
IEEE International Conference on Multimedia and Expo (ICME), 2025. Oral presentation.
- C11
- C12
- C13
- C14
Most Important Person-Guided Dual-Branch Cross-Patch Attention for Group Affect Recognition
IEEE/CVF International Conference on Computer Vision (ICCV), 2023.
- C15
AU-Assisted Graph Attention Convolutional Network for Micro-Expression Recognition
in Proceedings of the 28th ACM International Conference on Multimedia (MM), 2020, pp. 2871–2880.
- C16
Learning to Prompt for Vision-Language Emotion Recognition
in Affective Computing and Intelligent Interaction (ACII), AHRI workshop, 2023.
- C17
Refining Valence Arousal Estimation With Dual-Stream Label Density Smoothing
in International Conference on Consumer Electronics (ICCE), 2024.
- C18
Facial Chirality: Using Self-Face Reflection to Learn Discriminative Features for Facial Expression Recognition
in 2021 IEEE International Conference on Multimedia and Expo (ICME), IEEE,2021, pp. 1–6.
- C19
MER-GCN: Micro-Expression Recognition Based on Relation Modeling With Graph Convolutional Networks
in 2020 IEEE Conference on Multimedia Information Processing and Retrieval (MIPR), IEEE, 2020, pp. 79–84.
03 / People
Hongxia Xie谢洪霞
Principal Investigator, AVC Lab
hongxiaxie@jlu.edu.cn ↗
Associate Professor · Jilin UniversityHongxia Xie is an Associate Professor in the College of Computer Science and Technology at Jilin University and the principal investigator of AVC Lab. Her research spans affective computing, multimodal learning, generative AI, and socially aware embodied intelligence.
She received her Ph.D. from National Yang Ming Chiao Tung University, advised by Wen-Huang Cheng and co-advised by Hong-Han Shuai.
Our group combines close mentorship, open discussion, and careful experimentation. We welcome curious researchers who want to connect human understanding with advances in visual and embodied intelligence.
Ph.D. students
- Ruoxuan Zhang ↗张若萱Fall 2025
- Xinhui Yin尹馨慧Fall 2026
Master's students
- Zihan Li李子涵Fall 2025
- Yusen Xie谢玉森Fall 2025
- Mengyuan Wang王梦圆Fall 2026
- Jiaqi Shen沈佳琪Fall 2026
- Yiming Chen陈一鸣Fall 2026
Undergraduate students
- Qiyun Zheng郑淇匀2025–2026
- Ziqi Liao廖梓琪2025–2026
- Siyu Wu吴思雨2025–2026
- Zeyu Liang梁泽宇2025–2026
- Zhengguang Wang王争光Undergraduate student
- Chenghao Yu俞诚浩Undergraduate student
- Yifan Duan段逸凡Undergraduate student
Alumni
- Songhan Zuo左松函2024–2025
- Zhiyu Zhou ↗周志宇2025–2026
- Bin Wen ↗文彬2024–2026
- Cheng Zhang张成2024–2026
Teaching
- Cutting-Edge Research Introduction in Computer ScienceSpring 2024–2026
- Introduction to Artificial IntelligenceFall 2024 & 2025
- Pattern RecognitionSpring 2026
Academic service8 roles
- Tutorial Co-chairChinese Conference on Affective Computing (CCAC) 2026
- Digital Media Chair12th IEEE International Conference on Cybernetics and Intelligent Systems (CIS) and 12th IEEE International Conference on Robotics, Automation and Mechatronics (RAM), 2026
- Grand Challenge Co-chairACM Multimedia 2025
- Technical Committee MemberIEEE Consumer Technology Society (CTSoc)
- Executive Committee MemberMultimedia Technical Committee of the China Computer Federation (CCF-MM)
- Web ChairIEEE ICME 2022
- Web ChairACM ICMR 2021
- ReviewerECCV 2026; CVPR 2024–2026; ACM Multimedia 2021–2026; ICME 2021–2024; IEEE Transactions on Image Processing (TIP); IEEE Transactions on Multimedia (TMM); ACM Transactions on Multimedia Computing, Communications, and Applications (TOMM).
04 / TutorialsTutorials for beginners.
Research training and learning resources from AVC Lab.
Our lab’s official WeChat account is AVCLab_JLU. We regularly share accessible insights into our latest research progress. Feel free to follow us!
We provide regular training sessions for beginners, covering topics such as basic deep learning concepts, diffusion models, and more.
We provide research training for freshmen, and the related resources are available on our bilibili website.
Tutorial videos
Chinese-language recordings
01Generative AI Introduction to Diffusion Models
Watch on Bilibili ↗02Large Reasoning Models Introduction to GRPO and Related Work
Watch on Bilibili ↗03Embodied AI Introduction to Embodied AI
Watch on Bilibili ↗If you have any questions, please get in touch with us by email: hongxiaxie@jlu.edu.cn
05 / TalksInvited talks.
Research perspectives, practical AI education, and conversations with the wider community.
- 2026/05
MindPower: Enabling Theory-of-Mind Reasoning in VLM-based Embodied Agents
invited talk at the China Society of Image and Graphics (CSIG) Paper Sharing Seminar, hosted by Harbin Institute of Technology, China.
- 2026/03
Hands-On Experience with OpenClaw in Academic Research and Teaching Management
invited talk at the College of Automotive Engineering, Jilin University, China.
- 2025/12
Towards Building Mind-Reading Embodied Agents
invited talk at CSIG Affective Intelligence Conference 2025, Shenzhen, China.
- 2025/11
Emotion, Art, and Mind: A New Journey of Affective Computing in the Era of Large Models
invited talk at CIPS-SMP 2025, Wuhan, China.
- 2025/10
Seeing with Feeling: Visual Emotion Understanding in the LLM Era
Keynote Speaker at MRAC’25: Affective Computing Meets Large Language Models Workshop, ACM Multimedia 2025, Dublin, Ireland.
- 2025/07
CookAnything: Teaching Models to Cook Visually Step by Step
invited by Prof. Tan Yap Peng, NTU, Singapore.
- 2025/03–07
Innovative Applications of DeepSeek and Large Models for Enhancing Grassroots Work Efficiency
(DeepSeek等大模型提升基层工作效率的创新应用), invited talk at the “On-Site Training” Special Program for Community Workers organized by the Central Social Work Department of China (中央社会工作部(中社部)“送课上门”社区工作者专项培训(呼和浩特、西安、兴安盟、延安)
- 2025/06
AI Tools for Empowering Efficient Teaching
invited by Liwang Primary School, China.
- 2025/05
From DeepSeek to Deep Research: Paradigm Shifts in Scientific Inquiry Driven by Large Models
invited talk at the School of Business and Management, Jilin University, China.
- 2025/03
AI-Enabled Intelligent Office Transformation
invited talk at the Talent Affairs Office of Jilin University, China.
- 2025/03
LLMs Empowering Financial Intelligence: Innovative Applications for Enhancing Financial Office Efficiency
invited talk at the Finance Department of The First Bethune Hospital of Jilin University.
- 2025/03
A Tutorial to Core Technologies and Practical Applications of LLMs
invited talk at Jiaxin Technology, China.
- 2025/02
Visual Emotion Understanding: Opportunities and Challenges in the LLM Era
invited by Prof.Sanghoon Lee, Yonsei University, Korea.
- 2025/02
DeepSeek Technical Insights and Applying LLMs for Teaching Empowerment
Computer Science Faculty Teaching and Educational Capacity Enhancement Series Talks, Jilin University, China.
06 / Join usHelp shape what comes next.
Prospective students, research assistants, and collaborators are welcome. If our research resonates with your interests, we would be glad to hear from you.
FALL 2027 OPPORTUNITIES
1–2 Ph.D. openings · 3 master's openings
Remote research assistants welcome.
Contact Hongxia Xie → hongxiaxie@jlu.edu.cnPI of the AVC Lab

I lead the Affective and Vision Computing (AVC) Lab starting in 2024. Although it is a newly established team, it is full of energy. Currently, we have about 30 students, most of whom are undergraduates at Jilin University. We recruit research assistants year-round. If you are interested in joining our lab, please feel free to get in touch.


